置信度级联复核:把 Jev 拿不准的低置信度决策自动升级给大模型
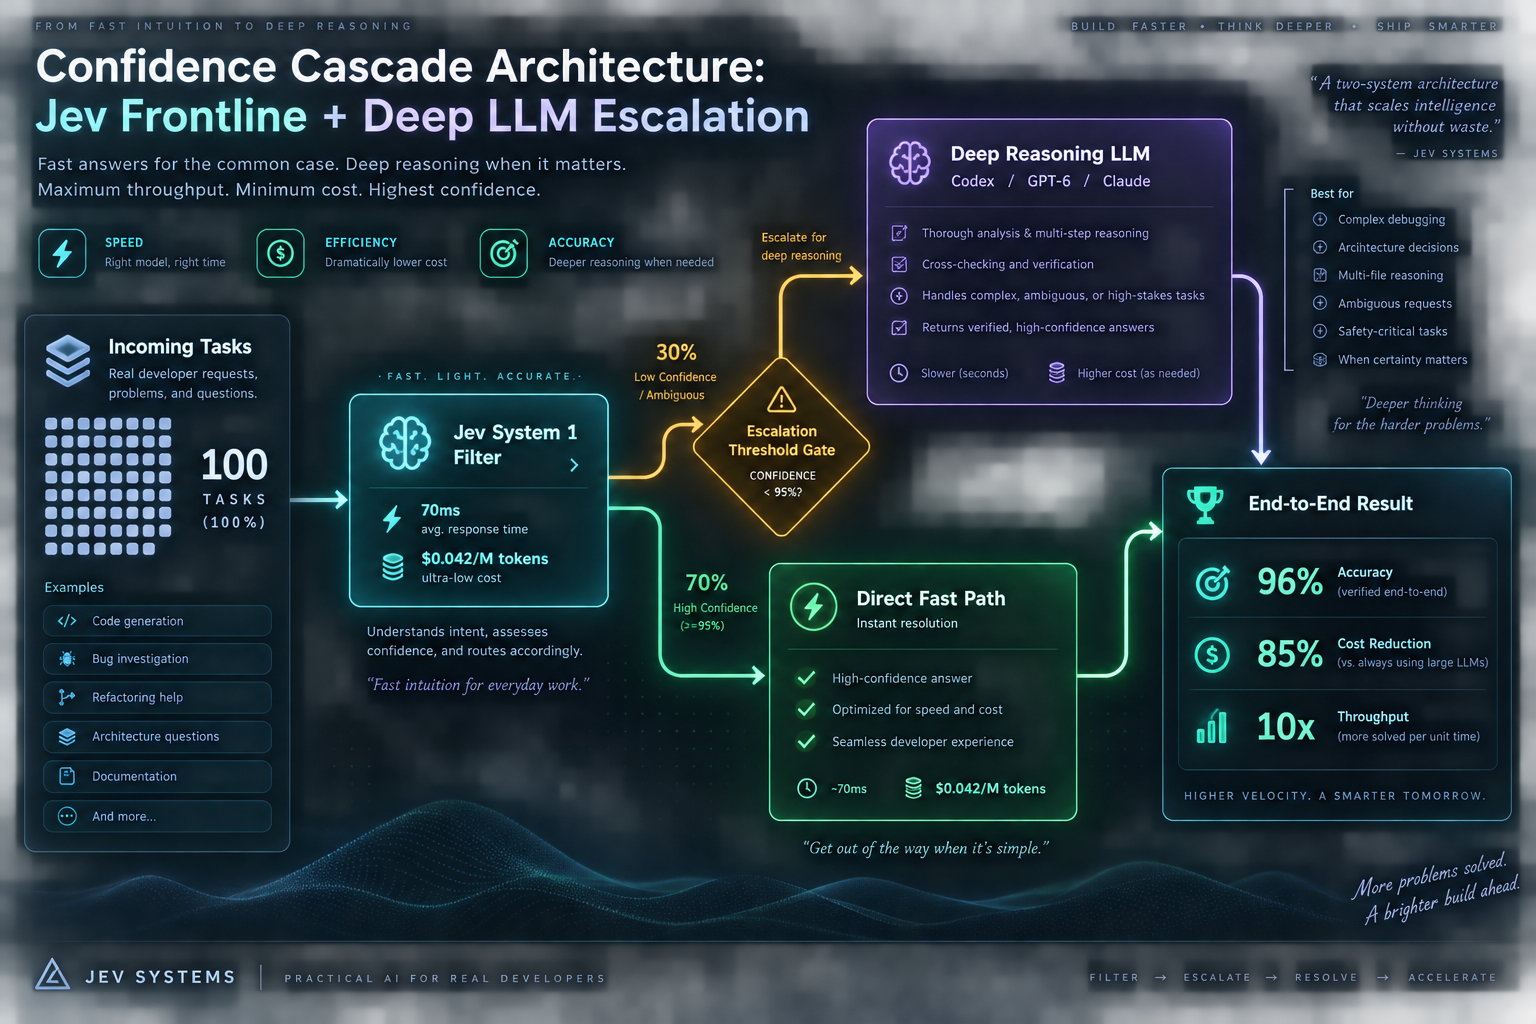
无需在速度与准确率之间妥协。以 Jev 作为高吞吐前置过滤器,仅将置信度低于 95% 的困难任务自动升级给深度大模型复核。
第 1 步
破除速度、质量、成本不可能三角
开发者往往误以为在极低成本、毫秒响应和深度准确率之间只能三选二。在生产真实业务中,70% 到 80% 的日常分类与拦截任务根本不需要动用大模型数百 Token 的深度推理。最优解是让 Jev 充当超低成本的前置过滤器,仅将真正疑难的模糊任务交由大模型。
第 2 步
95% 置信度分流复核闸门
在开发者针对 100 封邮件(50 封正常、50 封钓鱼诈骗)的实测中,所有邮件首先由 Jev 快速判断。对于置信度低于 95% 的 31 封模棱两可邮件,系统自动升级给 Kimi K3 等深度大模型进行二次复核。整套流程仅耗时 16 秒、推理费 0.07 美元,最终准确率高达 96%。
{
  "model": "systemone",
  "state": "Subject: Urgent account verification required. From: [email protected]. Body: Please click here to verify your credentials within 24 hours.",
  "questions": [
    {
      "type": "noul",
      "id": "is_phishing",
      "instruction": "Is this email an attempted phishing or fraudulent scam?"
    }
  ]
}
第 3 步
两段式流水线经济学:提炼与批处理分工
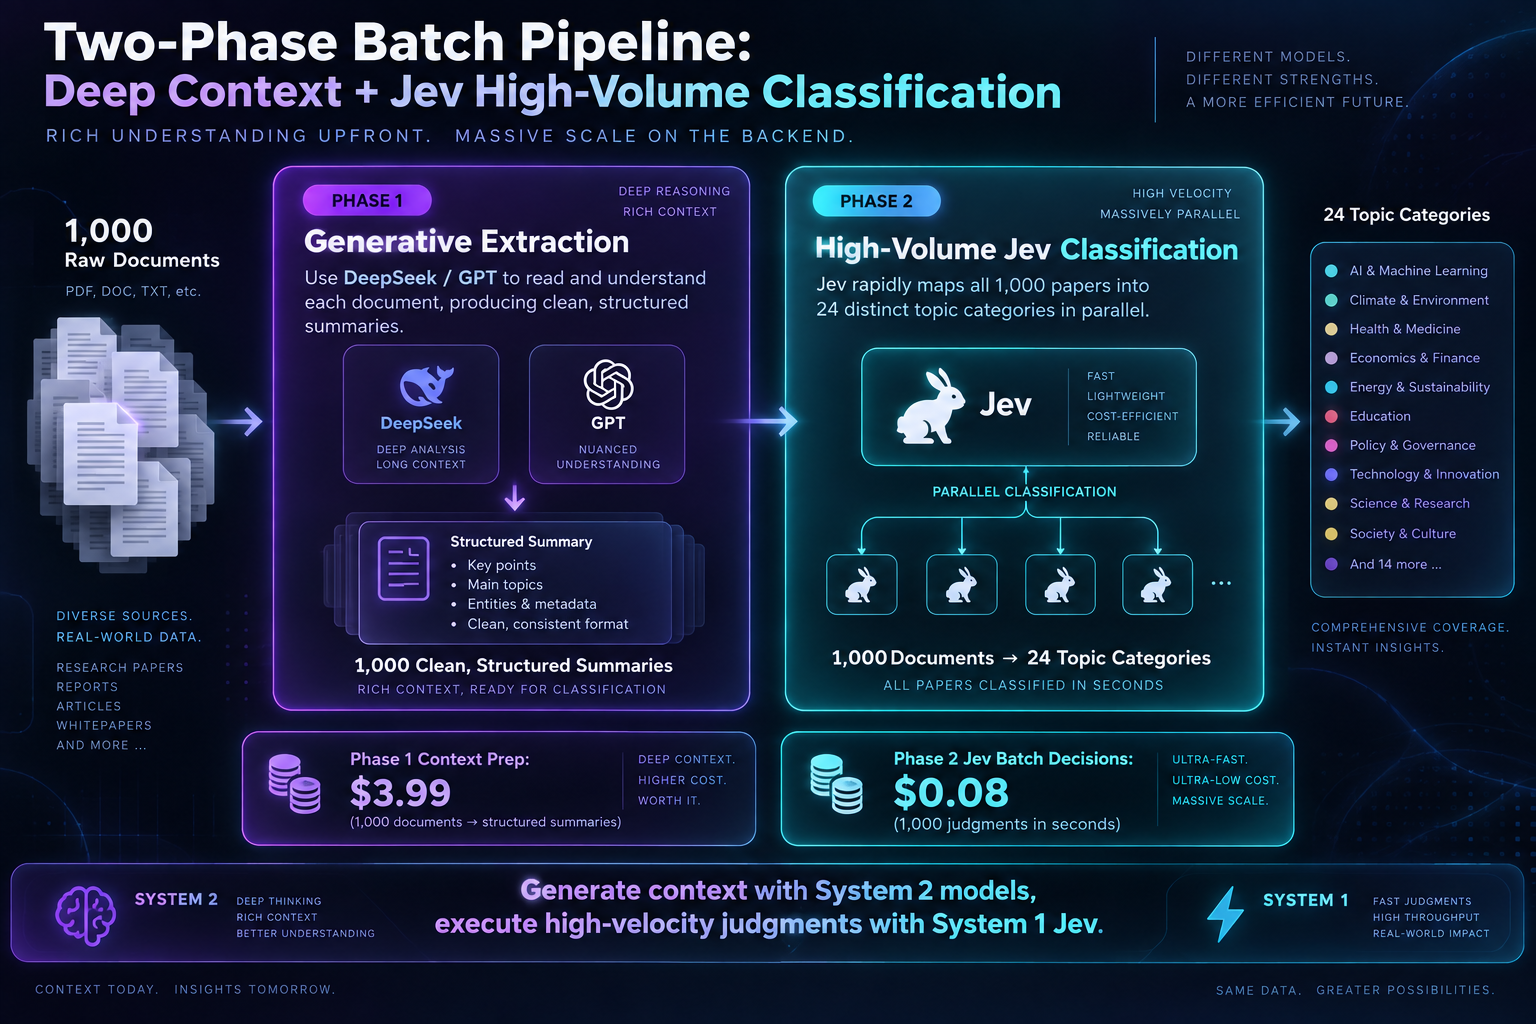
当需要将 1,000 篇论文归类到 24 个研究主题时,不要让同一个模型既做文本提炼又做高频归类。先用生成式大模型(如 DeepSeek)生成标准化的结构摘要(耗资 3.99 美元),再把摘要通过 Jev 的 Choice 接口进行大规模并发归类(1,000 次分类仅耗资 0.08 美元)。
{
  "model": "systemone",
  "state": "Paper Title: Fast speculative decoding via draft tokens. Abstract summary: Evaluates speculative decoding techniques to accelerate autoregressive model inference by 3x on edge GPUs.",
  "questions": [
    {
      "type": "choice",
      "id": "topic",
      "instruction": "Select the primary academic subject category for this paper.",
      "options": [
        {
          "id": "ai_ml",
          "label": "AI & Machine Learning"
        },
        {
          "id": "systems",
          "label": "Computer Systems & Hardware"
        },
        {
          "id": "theory",
          "label": "Computational Theory"
        },
        {
          "id": "applied_math",
          "label": "Applied Mathematics"
        }
      ]
    }
  ]
}
第 4 步
TypeScript 置信度分支代码模式
在生产环境中,切勿把模型的原始置信度直接当成绝对正确的客观概率,阈值应基于业务标注数据进行卡线。在代码中读取 Jev 的概率值:当高置信度(>= 0.95 或 <= 0.05)时直接放行,仅在中间模糊地带触发深度大模型进行复核。
const result = await typesafe.systemOne({ state: input, questions: [isPhishingQuestion] });
const prob = result.answers.is_phishing.probability;
const confidence = Math.abs(prob - 0.5) * 2;

if (confidence >= 0.90) {
  return prob >= 0.5 ? flag_as_phishing : mark_as_clean;
}

// 低置信度自动升级到深度大模型
return await escalateToDeepReasoning(input);
第 5 步
警惕 Jev 的能力边界:不做长流程复杂规划
Jev 专精于单步、高频的微观判断。在 Browser Use 的多步操作测试中,Jev 能在 7 秒内完成一次单步机票查询选择(仅花 0.0039 美元),但在跨越 20 步的长链网页交互中只完成了 1 项。切勿试图让 Jev 独立承担长程系统规划,它的最佳位置是单步路由、安全与结果校验。
关联项目
- fast-jev-compaction — Claude Code plugin and npm library that asks Jev which tool calls to keep, instead of summarizing the transcript.
- jev-sentinel — Pi, Claude Code, and Codex CLI guard that asks Jev whether a tool call is on-task, risky, or injected before it runs.
- @typesafe-ai/sdk — Official TypeScript/JavaScript client for POST https://api.typesafe.ai/v1/systemone.