Workflow guide
Confidence Cascades: Escalating Low-Certainty Decisions from Jev to Deep LLMs
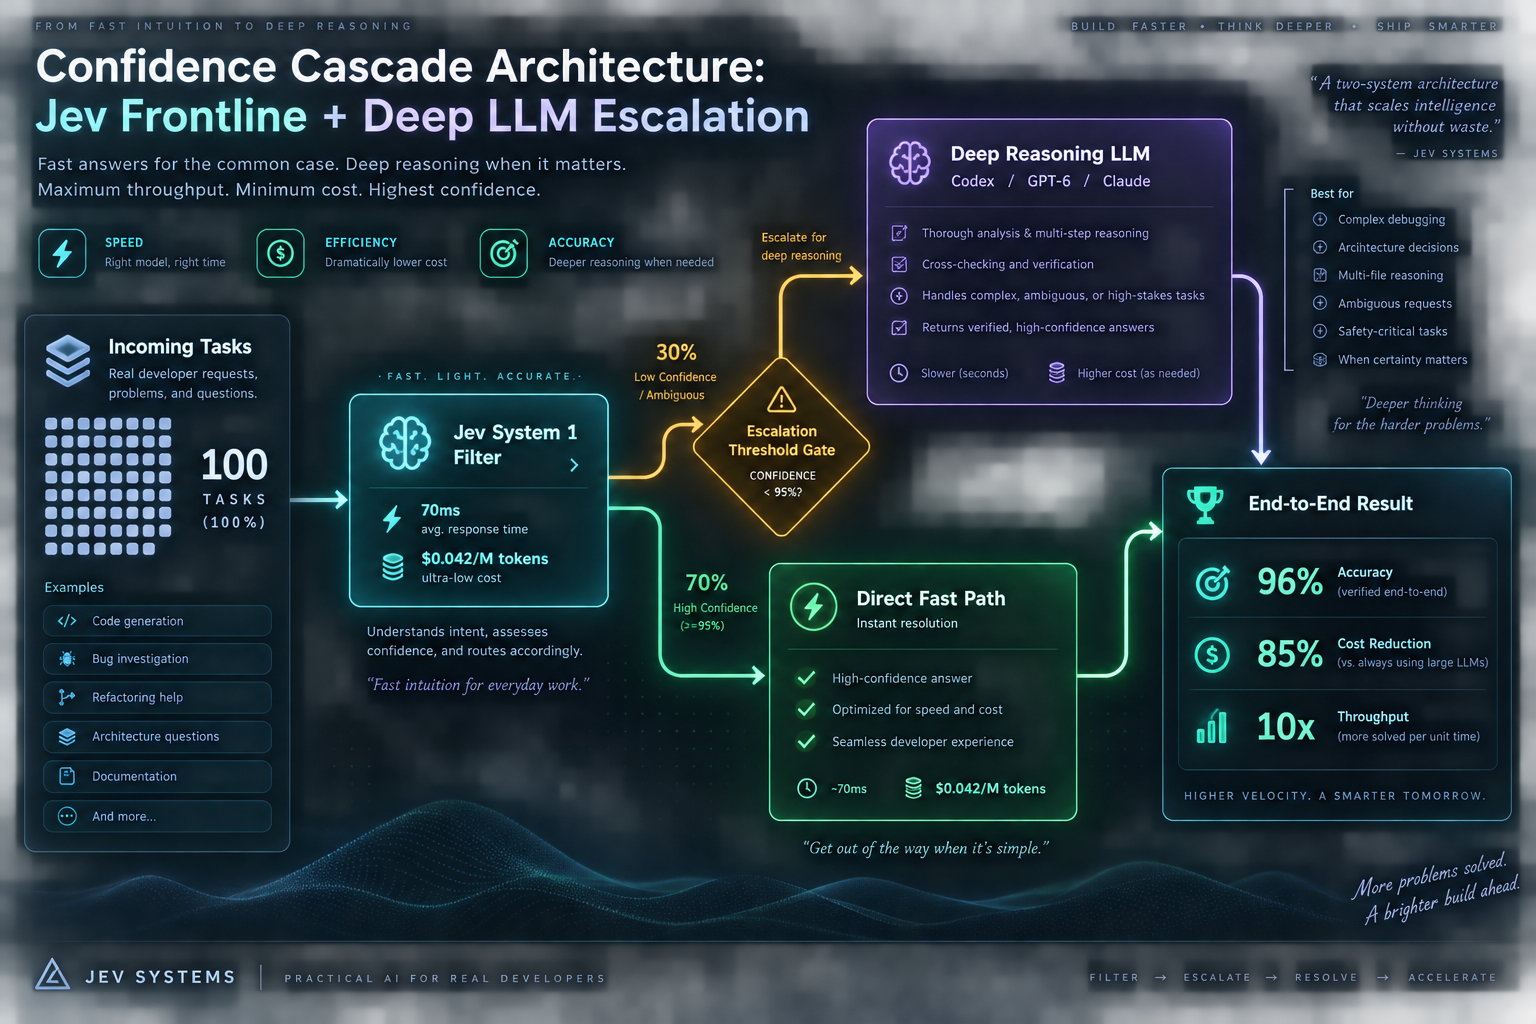
Do not choose between speed and accuracy. Use Jev as the high-throughput frontline filter, and automatically escalate decisions with sub-95% confidence to deep reasoning models for verification.
Step 1
The speed-quality false dilemma
Developers often assume they must pick between instant, low-cost responses and deep reasoning accuracy. In production, 70% to 80% of routine categorization and filtering tasks do not require hundreds of tokens of deliberation. The optimal design uses Jev as a high-speed frontline filter and only escalates ambiguous cases.
Step 2
The 95% confidence threshold gate
In developer experiments with 100 emails (50 normal, 50 phishing), Jev evaluated every message first. Cases where Jev's output probability fell into ambiguous ranges (confidence < 95%, about 31 emails) were automatically escalated to deep reasoning models like Kimi K3 or GPT-6. The cascade achieved 96% end-to-end accuracy in 16 seconds for /bin/zsh.07.
{
  "model": "systemone",
  "state": "Subject: Urgent account verification required. From: [email protected]. Body: Please click here to verify your credentials within 24 hours.",
  "questions": [
    {
      "type": "noul",
      "id": "is_phishing",
      "instruction": "Is this email an attempted phishing or fraudulent scam?"
    }
  ]
}
Step 3
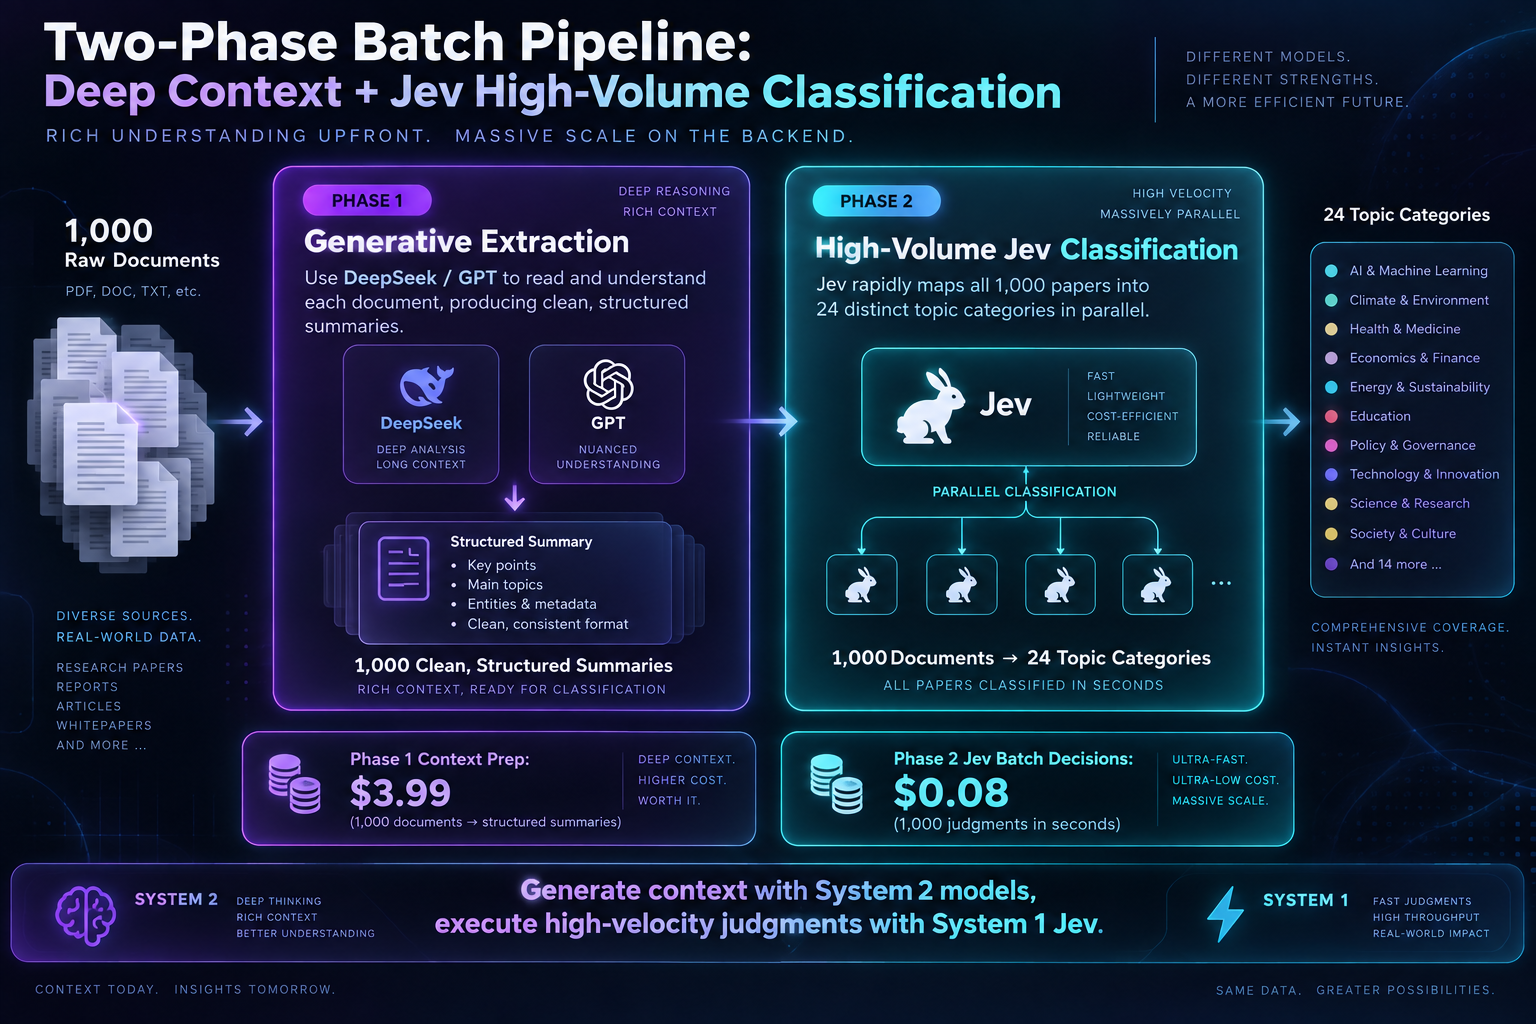
Two-phase batch pipeline economics
When classifying 1,000 research papers into 24 distinct topic categories, do not force one model to do both synthesis and high-volume classification. Use a generative LLM (such as DeepSeek) once to produce standardized structured summaries (.99), then stream those summaries through parallel Jev Choice questions to assign all 1,000 topics in seconds for just /bin/zsh.08.
{
  "model": "systemone",
  "state": "Paper Title: Fast speculative decoding via draft tokens. Abstract summary: Evaluates speculative decoding techniques to accelerate autoregressive model inference by 3x on edge GPUs.",
  "questions": [
    {
      "type": "choice",
      "id": "topic",
      "instruction": "Select the primary academic subject category for this paper.",
      "options": [
        {
          "id": "ai_ml",
          "label": "AI & Machine Learning"
        },
        {
          "id": "systems",
          "label": "Computer Systems & Hardware"
        },
        {
          "id": "theory",
          "label": "Computational Theory"
        },
        {
          "id": "applied_math",
          "label": "Applied Mathematics"
        }
      ]
    }
  ]
}
Step 4
Code pattern: Branching on confidence in TypeScript
Calibrate your threshold on annotated domain data rather than treating raw model confidence as ground truth. In code, read Jev's probability value: proceed immediately when confidence is decisive (>= 0.95 or <= 0.05), and dispatch to your deep LLM pipeline only in the uncertain middle band.
const result = await typesafe.systemOne({ state: input, questions: [isPhishingQuestion] });
const prob = result.answers.is_phishing.probability;
const confidence = Math.abs(prob - 0.5) * 2;

if (confidence >= 0.90) {
  return prob >= 0.5 ? flag_as_phishing : mark_as_clean;
}

// Low-confidence escalation path
return await escalateToDeepReasoning(input);
Step 5
Know when Jev fails: Complex long-horizon planning
Jev excels at isolated, high-velocity micro-decisions. In Browser Use experiments, Jev navigated a simple flight lookup in 7 seconds for /bin/zsh.0039, but struggled on 20-step multi-page workflows (finishing only 1 of 20 tasks). Do not use Jev for stateful long-horizon task planning; reserve it for single-step routing, scoring, and verification.
Related projects
- fast-jev-compaction — Claude Code plugin and npm library that asks Jev which tool calls to keep, instead of summarizing the transcript.
- jev-sentinel — Pi, Claude Code, and Codex CLI guard that asks Jev whether a tool call is on-task, risky, or injected before it runs.
- @typesafe-ai/sdk — Official TypeScript/JavaScript client for POST https://api.typesafe.ai/v1/systemone.